Fine-grained visual recognition

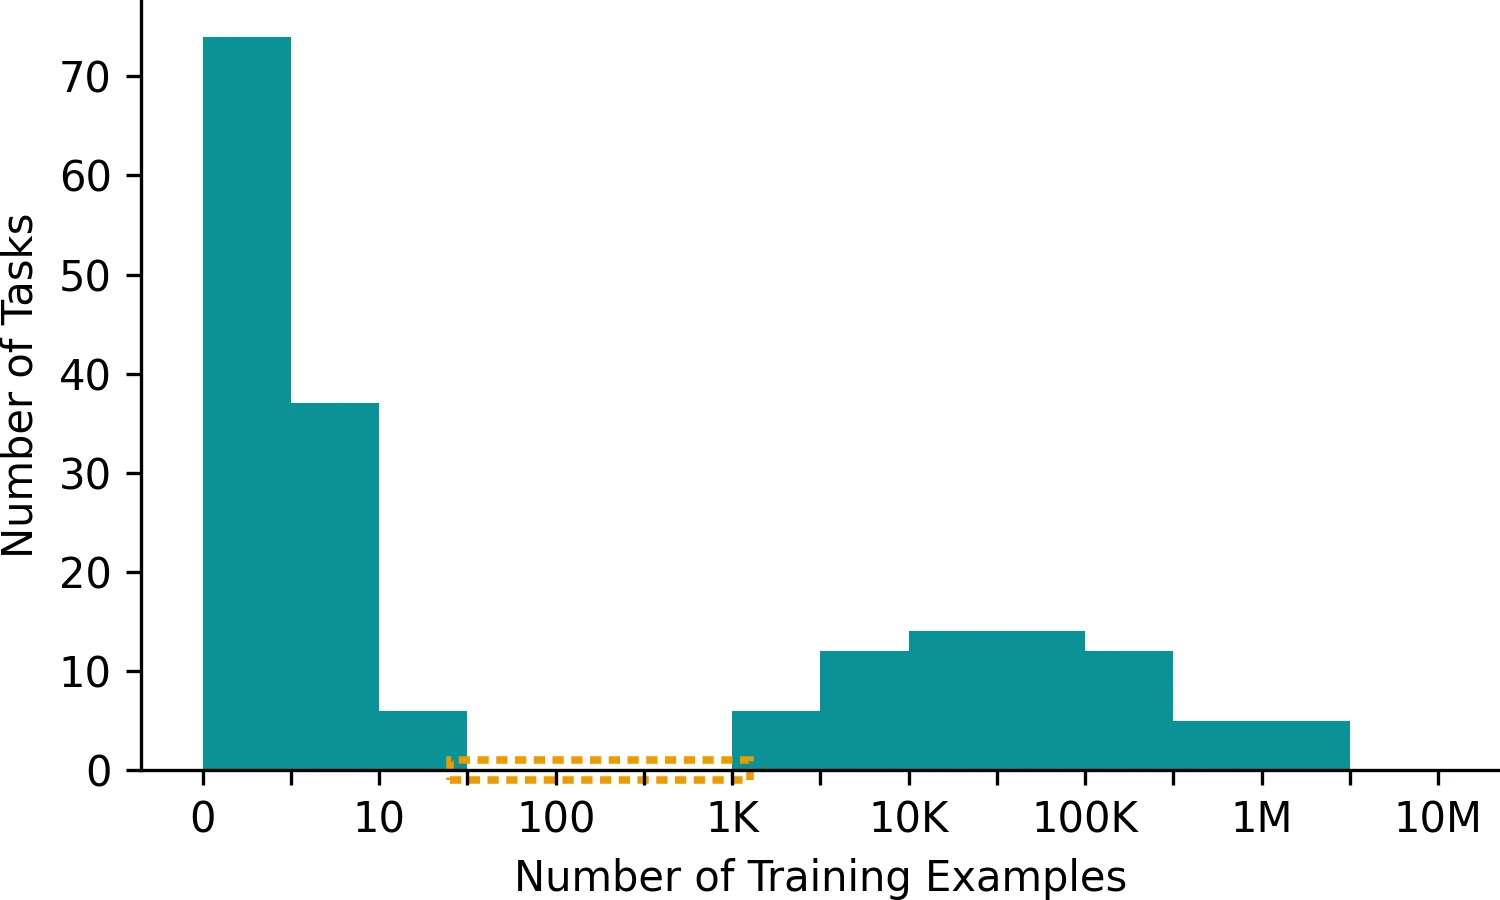
Fine-grained recognition is where vision models meet classes that differ in sub-millimeter detail, long-tailed label distributions and strong domain shift. I benchmark self-supervised, supervised and vision-language encoders with linear probing, measure sample efficiency, and test transfer from curated images to in-the-wild photographs, using ground beetle species as the test bed.

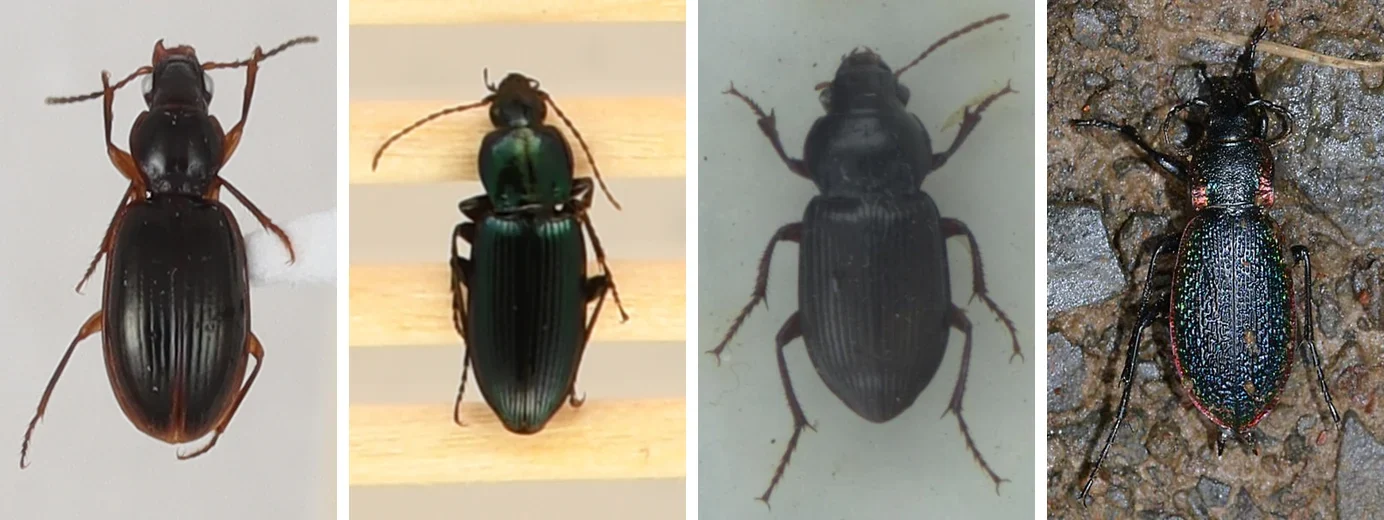
Project pageOne sample from each dataset, from curated lab images to field photographs: BeetlePUUM, BeetlePalooza, NHM-Carabids and I1MC.
ICCV 2025 WorkshopFirst author

Fine-Grained Beetle Taxonomy with Vision Models: A Benchmark on Long-Tailed and Domain-Adaptive Classification

S M Rayeed, Alyson East, Samuel Stevens, Sydne Record, Charles V. Stewart
ICCV 2025 Workshop on Computer Vision for Ecology (CV4E)

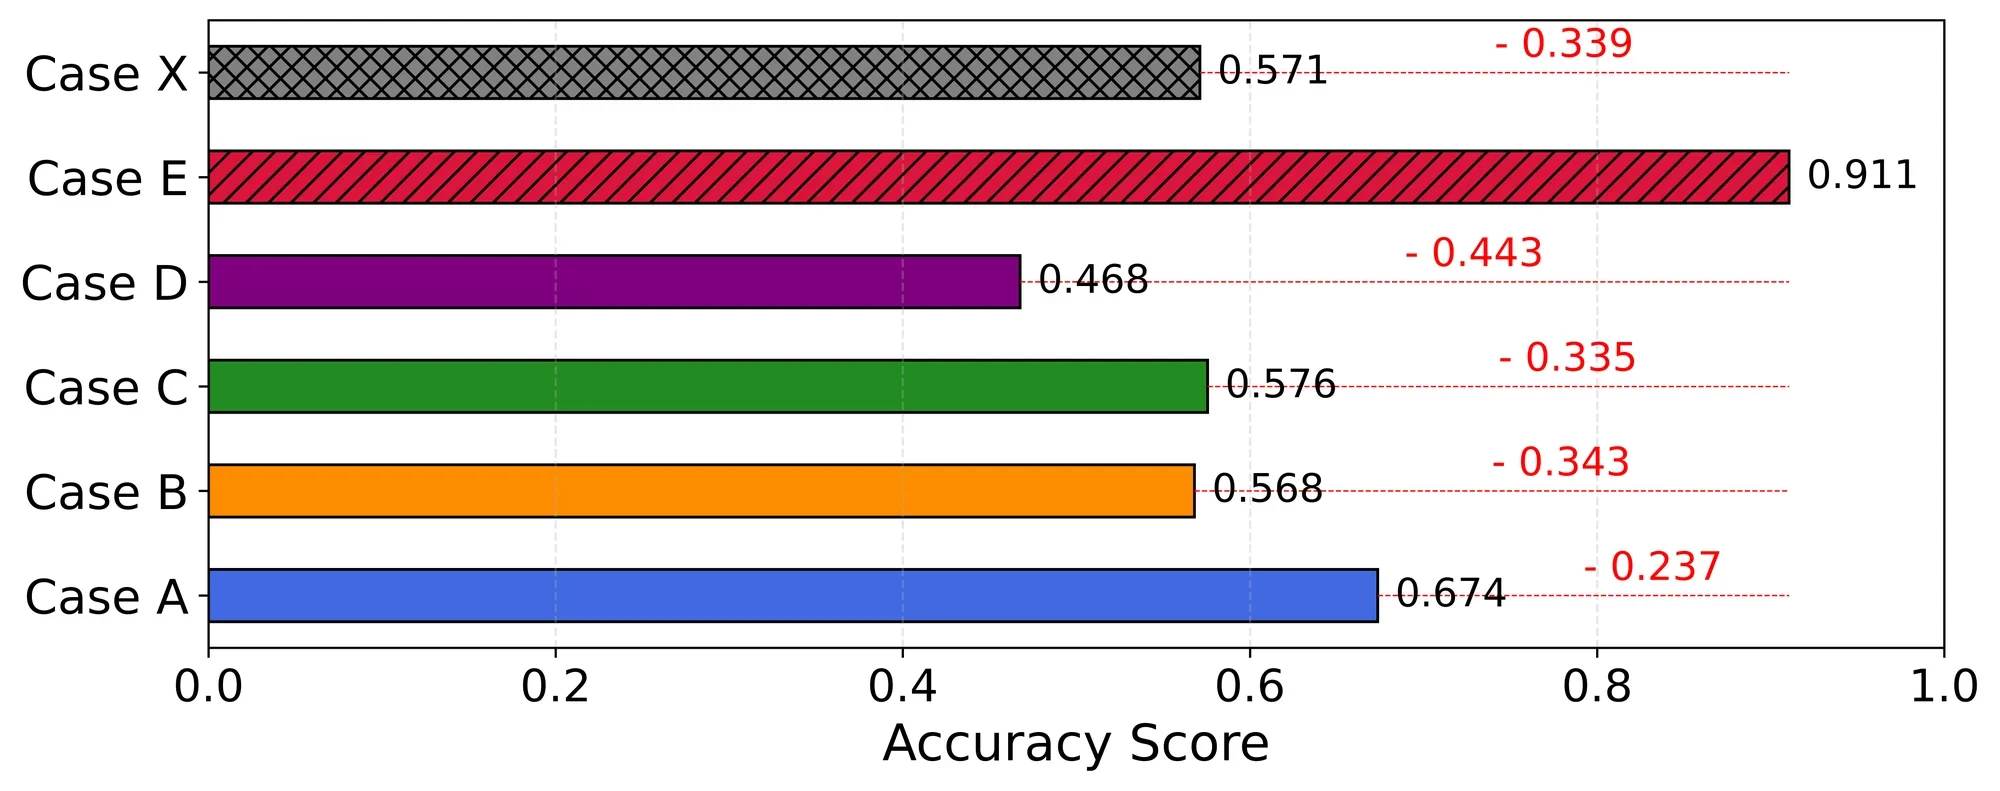
12 vision and vision-language encoders, linear-probed on about 100K images of 1,769 carabid species from four long-tailed datasets. ViLT reaches 97% genus and 94% species accuracy, half the training data costs little, and lab-to-field transfer drops 37%.
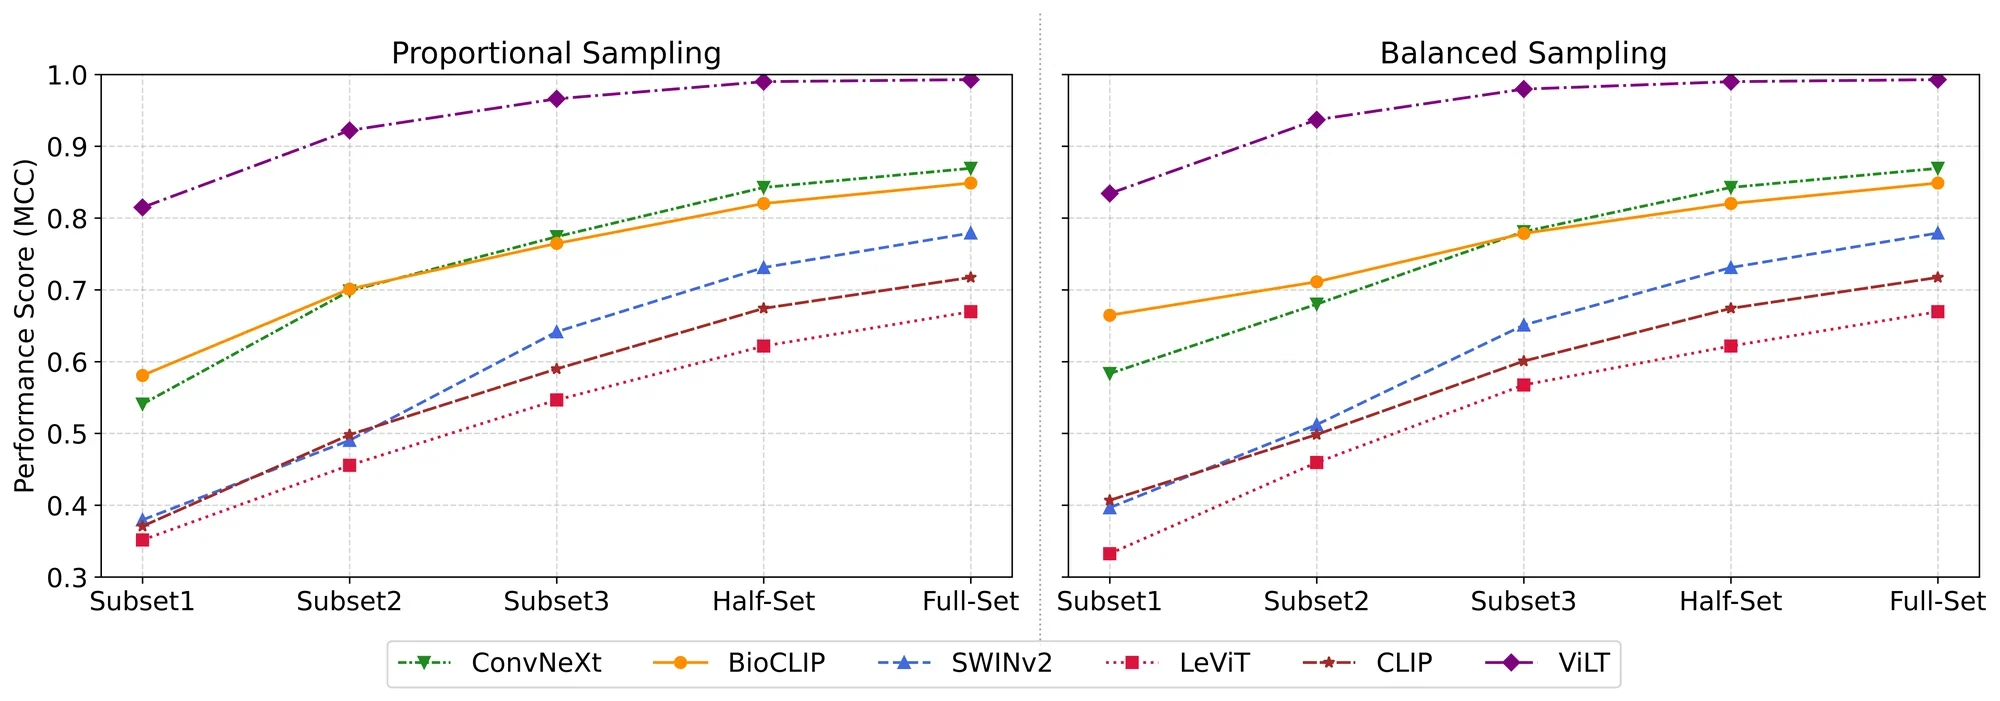
Linear-probe accuracy of each encoder as training data grows, under proportional and balanced sampling.
Cross-dataset transfer with ViLT: training on curated lab images and testing on field images loses up to a third of the accuracy.
Cross-dataset transfer with ViLT: models trained on curated lab images lose accuracy on field photographs.
CVPR 2025 WorkshopFirst author

BeetleVerse: A study on taxonomic classification of ground beetles

S M Rayeed, Alyson East, Samuel Stevens, Sydne Record, Charles V. Stewart
CVPR 2025 Workshop on CV4Animals

The first version of the benchmark, presented at CV4Animals: where frozen encoders succeed on curated collections, and how sharply they fail once the same species are photographed in the field.

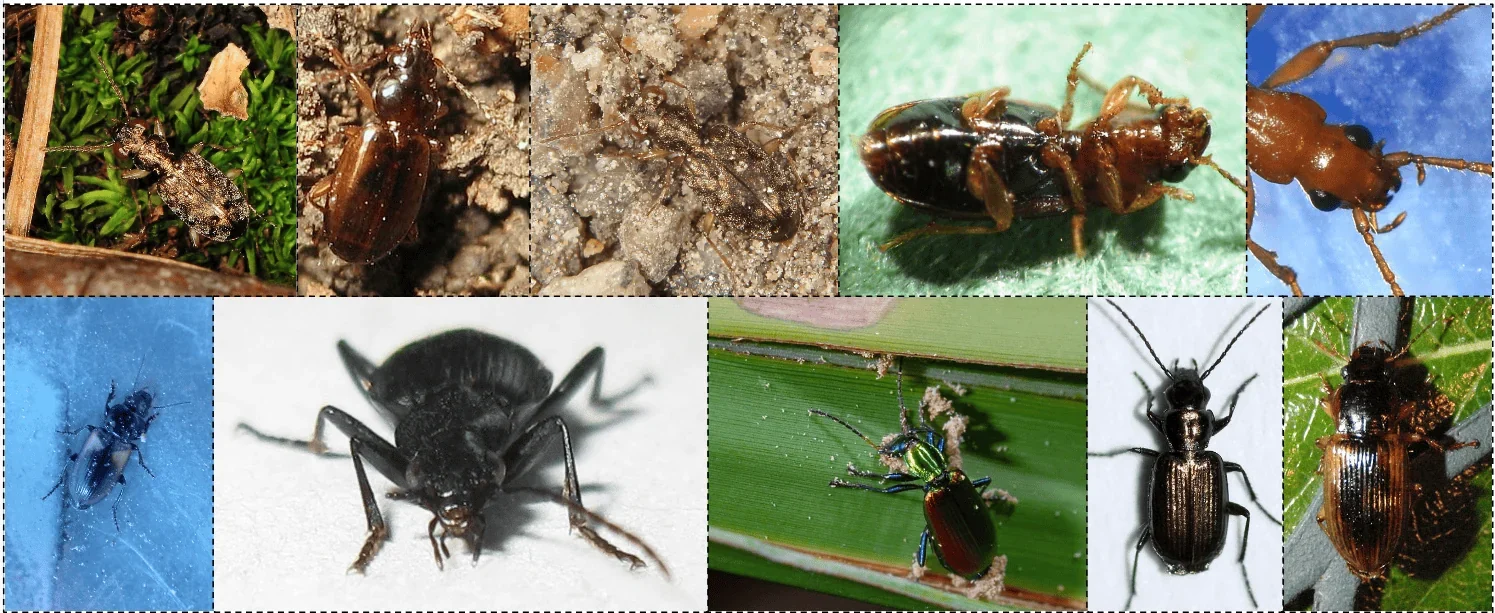
Field images in I1MC: cluttered backgrounds, varying viewpoints, occlusion and incomplete specimens.
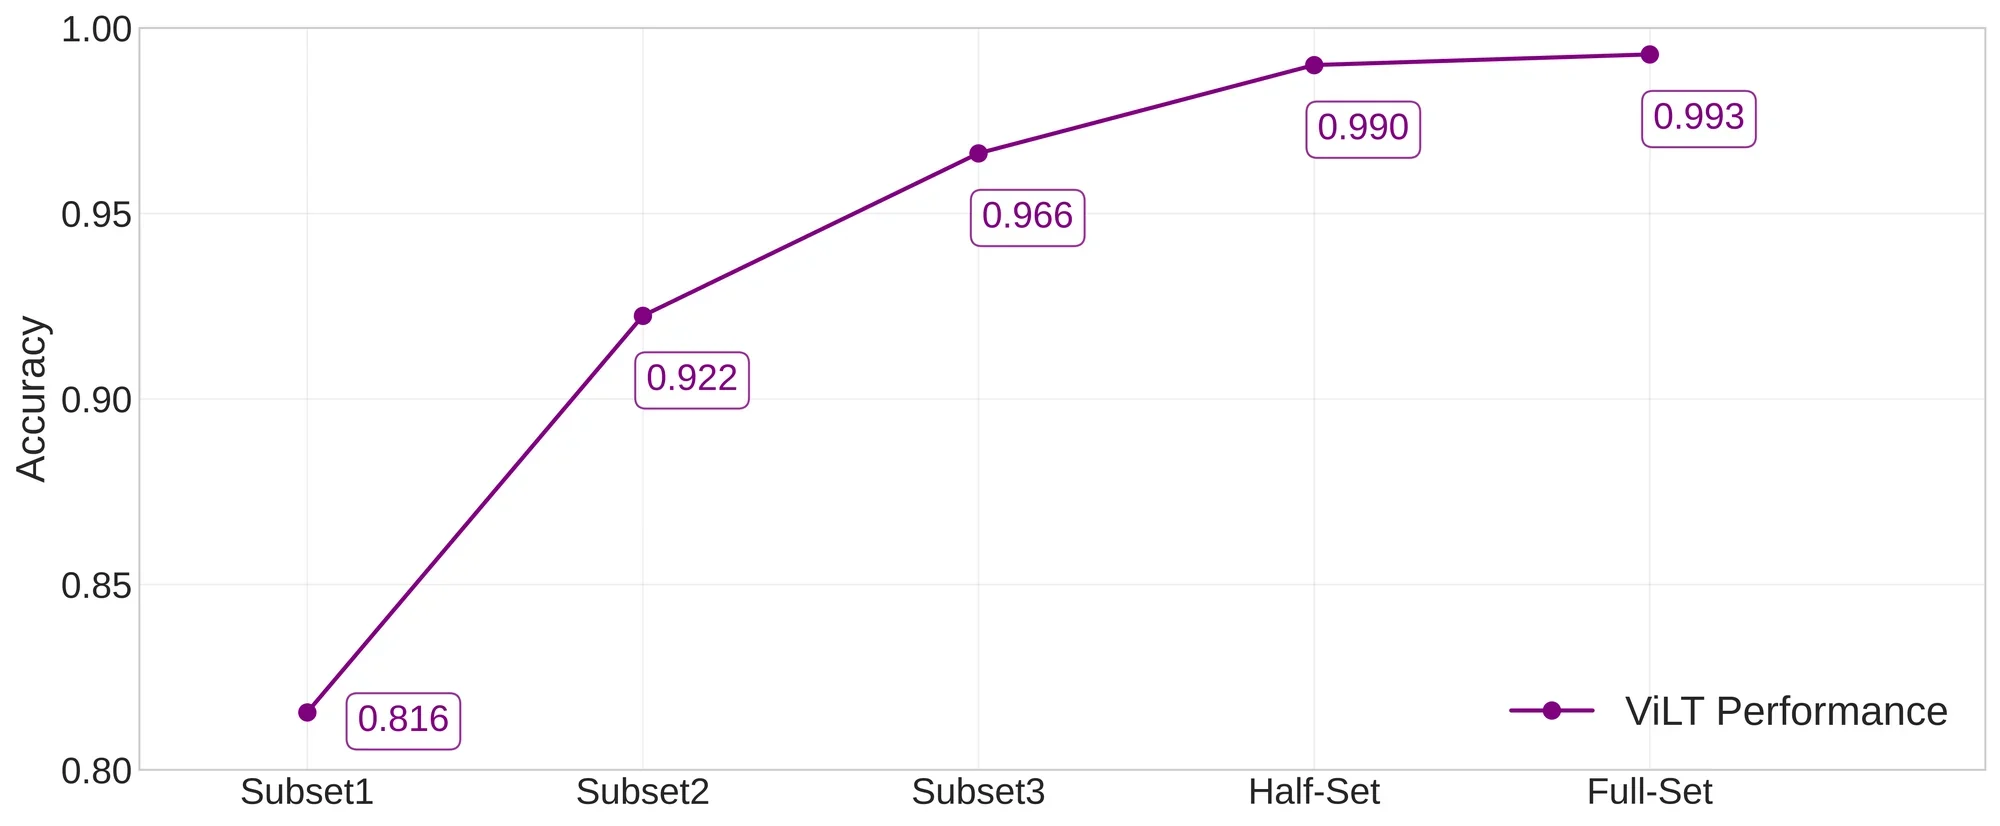
ViLT accuracy with growing subsets of the training data.

Other research areas