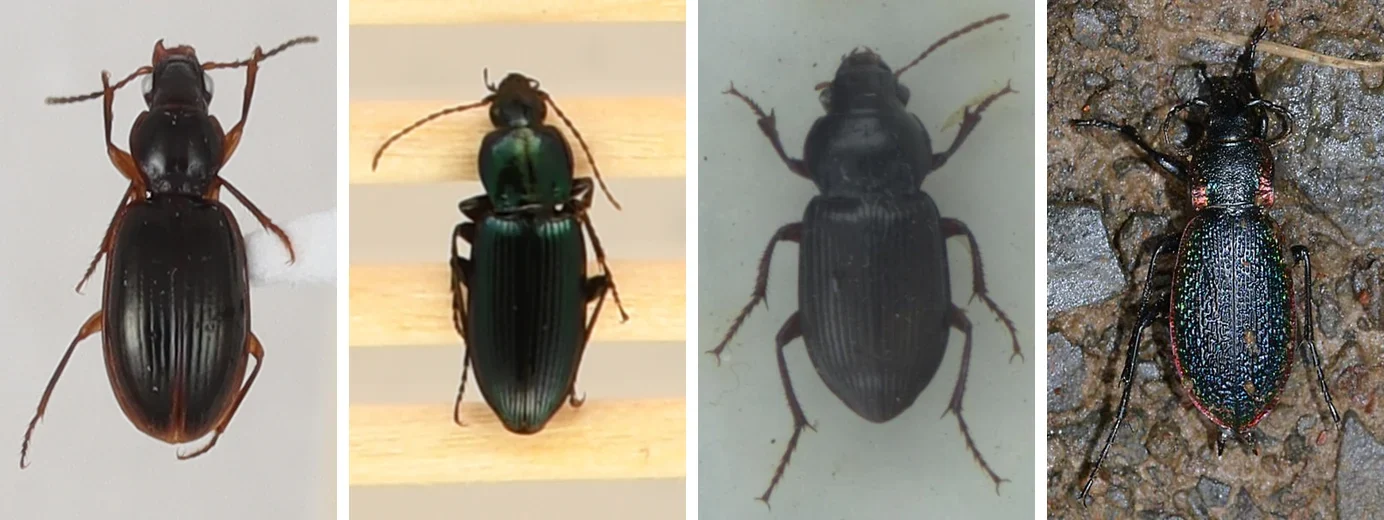
Fine-grained recognition benchmark
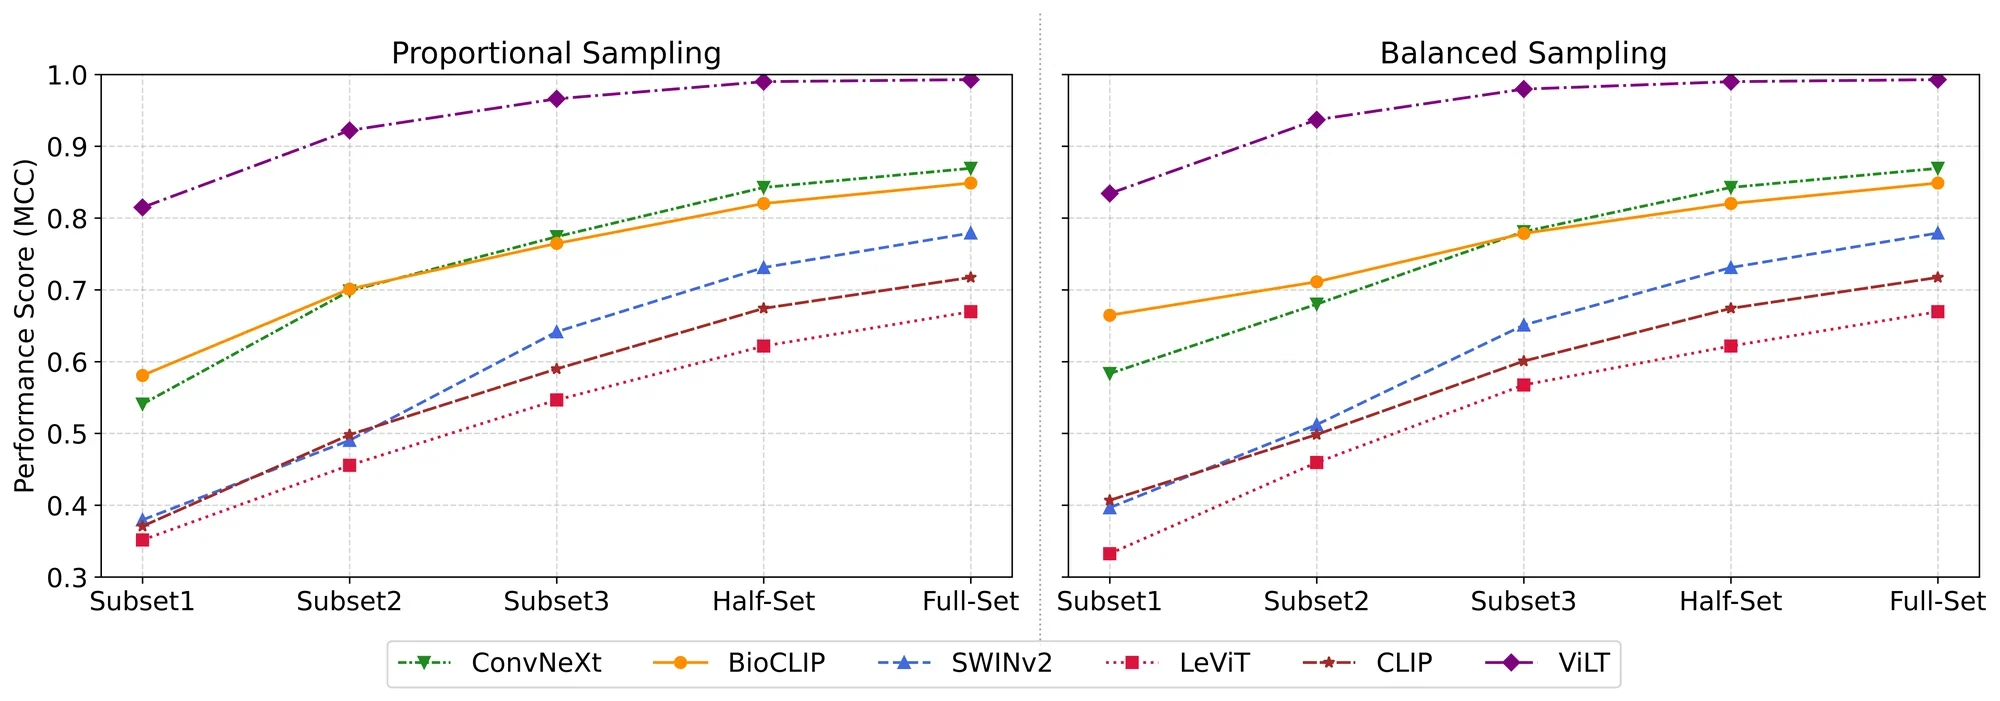
12 self-supervised, supervised and vision-language encoders, linear-probed on 100,885 images of 1,769 species from four long-tailed datasets. ViLT reaches 97.15% genus and 93.97% species accuracy; half the training data costs little accuracy; transfer from lab to field images drops by up to 37%.